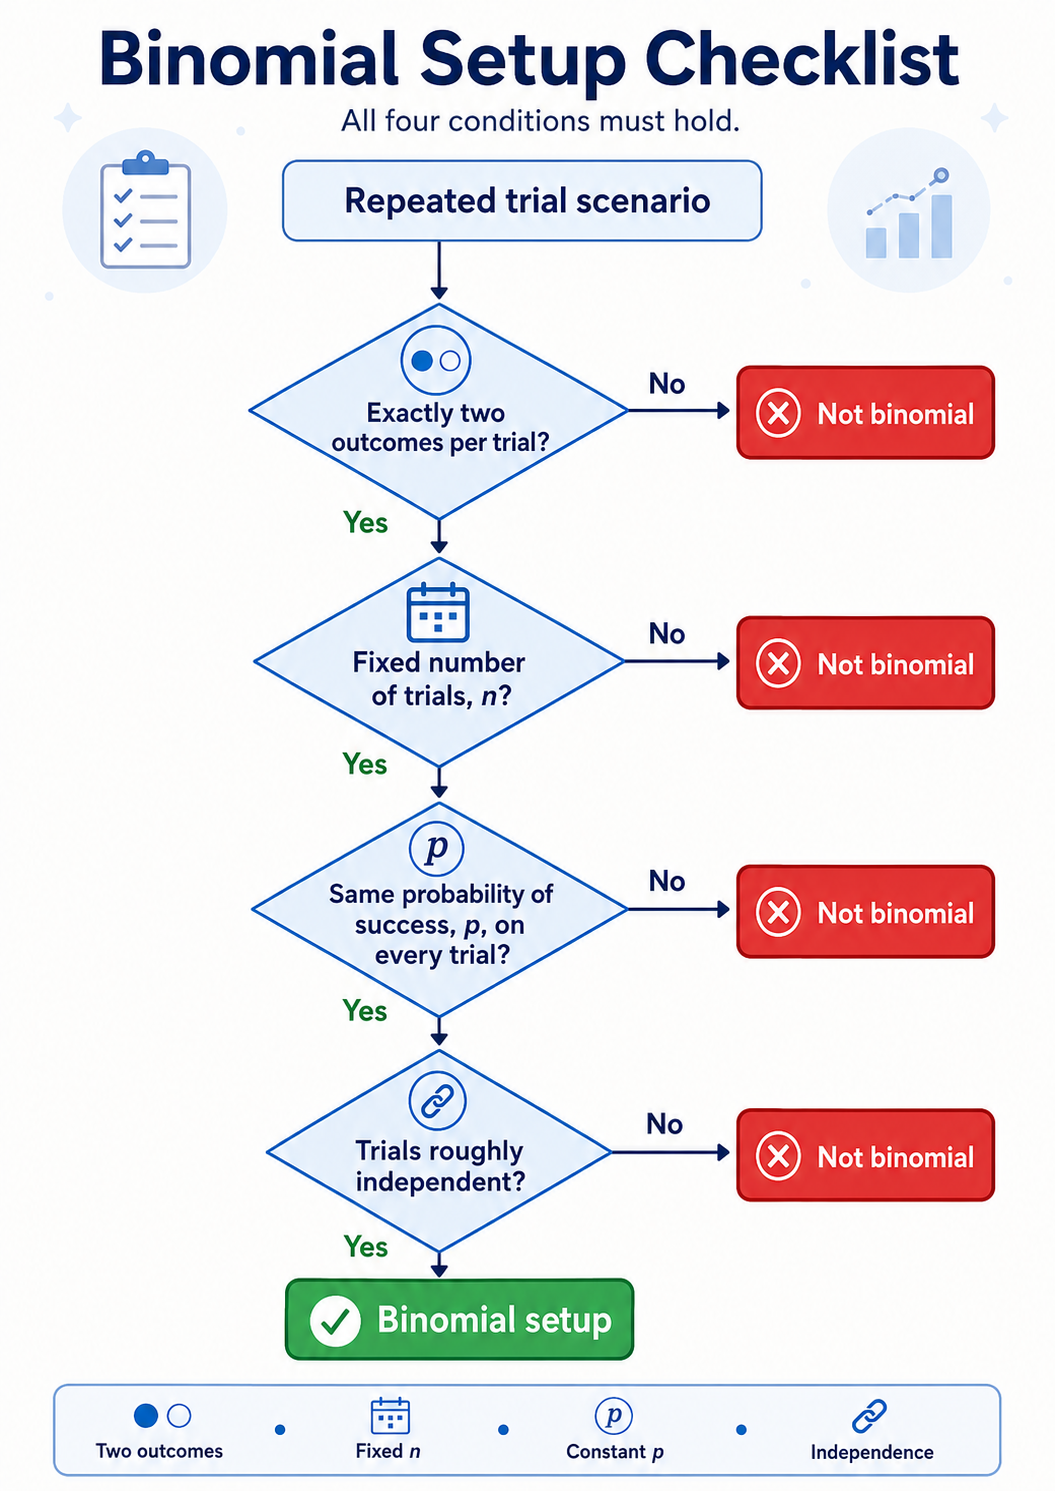
Repeated Yes No Trials
Introduction
Welcome to The Binomial Distribution, the fourth course in our learning path! In earlier courses, we explored how distributions work as maps of likelihood, examined the flat uniform shape, and studied the familiar bell curve of the normal distribution. Now we turn to a distribution that arises from one of the most common patterns in everyday life: repeating a simple yes-or-no process several times and counting how often a particular outcome occurs.
This first lesson focuses on the setup behind the binomial distribution. Before we look at any graphs or shapes, we need to understand exactly what kind of situation produces a binomial distribution in the first place. By the end, you will be able to check whether a real scenario meets all the required conditions.
From Observation to Repetition
The Two-Outcome Trial
The building block of every binomial situation is a single trial that has exactly two possible outcomes. We label one outcome success and the other failure. These labels are just conventions and carry no judgment — a "success" might be a defective item if defects are what we are counting.
Here are a few everyday examples of two-outcome trials:
- A customer either clicks a link or does not.
- A free-throw shot either goes in or misses.
- A seed either sprouts or fails to sprout.
If a trial can land on more than two distinct outcomes, it does not fit the binomial framework on its own. The key requirement is that every single trial collapses to exactly one of two categories.