Revisiting Sequence Models: RNNs, LSTMs, and Their Limits
Introduction
Hello there! Welcome to the first lesson of our course "Sequence Models & The Dawn of Attention". This initial lesson marks the beginning of an exciting journey that will take us from traditional sequence modeling approaches all the way to the cutting-edge Transformer architecture that powers today's most advanced AI systems.
Before we dive into our exploration of sequence models, let's establish what we expect you to bring to this course path. We assume you have solid foundations in Python programming, basic machine learning concepts, and PyTorch fundamentals, including tensor operations and neural network construction. Familiarity with basic linear algebra and calculus will also serve you well as we work through mathematical concepts.
Our learning path consists of four comprehensive courses designed to give you deep expertise in Transformer architectures. In this first Course, we'll explore why traditional RNNs and LSTMs struggle with long sequences and build attention mechanisms from scratch, mastering the query-key-value paradigm. Next, in Course 2 we'll systematically construct the complete Transformer architecture, creating reusable components such as multi-head attention modules, feed-forward networks, and positional encodings. By Course 3 we'll be able to combine everything into a complete Transformer model, implementing autoregressive training with teacher forcing and exploring different decoding and inference strategies. Finally, in the last Course we'll harness the powerful Hugging Face ecosystem to work with pre-trained models and fine-tune them for real-world applications.
By the end of this path, you'll have gained a profound understanding of how Transformers work under the hood and the practical skills to apply them effectively. Today, in our first lesson, we begin by revisiting sequence models to understand their limitations and why the AI community needed something better. Let's get started!
The Evolution of Sequence Modeling
Sequential data surrounds us everywhere: the words in this sentence follow a specific order, stock prices change over time, and DNA sequences encode genetic information through their arrangement. Traditional feedforward neural networks process each input independently, but sequence modeling requires understanding how current elements relate to previous ones.
The challenge lies in temporal dependencies: understanding that "the cat sat on the" should be followed by something like "mat" requires remembering context from earlier in the sequence. Early approaches like n-grams could only look back a fixed number of steps, severely limiting their ability to capture long-range relationships. This limitation sparked the development of recurrent architectures that could theoretically maintain information across arbitrary sequence lengths.
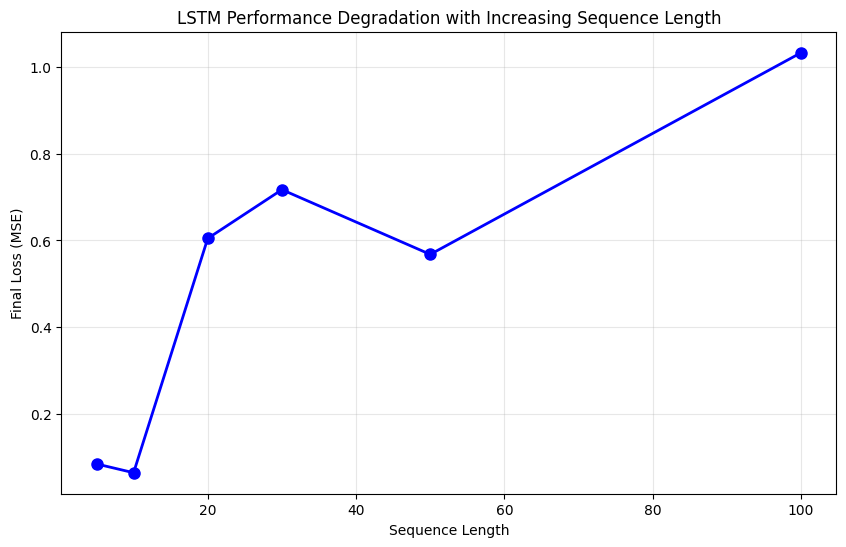
However, as we'll discover today, even sophisticated recurrent models face fundamental challenges when sequences grow long. This limitation will motivate the development of attention mechanisms and, later, of the Transformer architecture.