Choosing Where AI Helps at Work
Choosing Where AI Helps at Work 🧭
Now that you can tell the AI capabilities apart, the next move is harder and more useful: deciding which of your actual analytics tasks belong in an AI workflow and which ones absolutely don't. Choosing the right starting point matters. A use case that looks exciting but is hard to verify—like AI-written executive KPI commentary for a board pack—can drain time and put a wrong number in front of leadership, while overlooking practical everyday tasks can leave value untapped. This unit gives you a simple lens to sort your week and choose a first win you can defend.
By the end, you’ll be able to:
- Sort recurring analytics work into communication, research, planning, and analysis tasks.
- Evaluate AI candidates using Value, Risk, Repeatability, and Human Review.
- Select a low-risk pilot with a clear success criterion.
Mapping Your Work Into AI-Assistable Categories 🪣
Start by looking at a normal week and asking: what kind of analytics work keeps showing up? Most AI-assistable tasks fall into four practical buckets.
| Bucket | What It Means | Common Analytics Examples |
|---|---|---|
| Communication | Writing or shaping information for an audience | KPI readout narratives, stakeholder updates, metric documentation, weekly metrics digests |
| Research | Gathering and digesting information | Summarizing open-text survey comments, scanning docs for a metric definition, pulling statistical-method background |
| Planning | Structuring work before it happens | Drafting an analysis plan, breaking a reporting request into steps, building a readout template |
| Analysis | Making sense of inputs | Tagging themes in survey feedback, comparing options against criteria, sanity-checking a trend narrative |
Why bother sorting? Because each bucket has a different risk profile and a different verification cost. A draft stakeholder update may only need a quick tone check. A metric definition or a statistical claim may need a source. If you don’t separate these task types, you may treat every AI output the same way, which is exactly how a confident-but-wrong number slips into a readout or a dashboard.
Try This: Take ten minutes this week and list five recurring analytics tasks under each bucket. That list becomes the candidate pool for everything that follows.
The AI Task Fit Screen 🤖
Once you have candidates, run each one through the AI Task Fit Screen, four quick checks that tell you whether a task is a fit, a maybe, or a hard no.
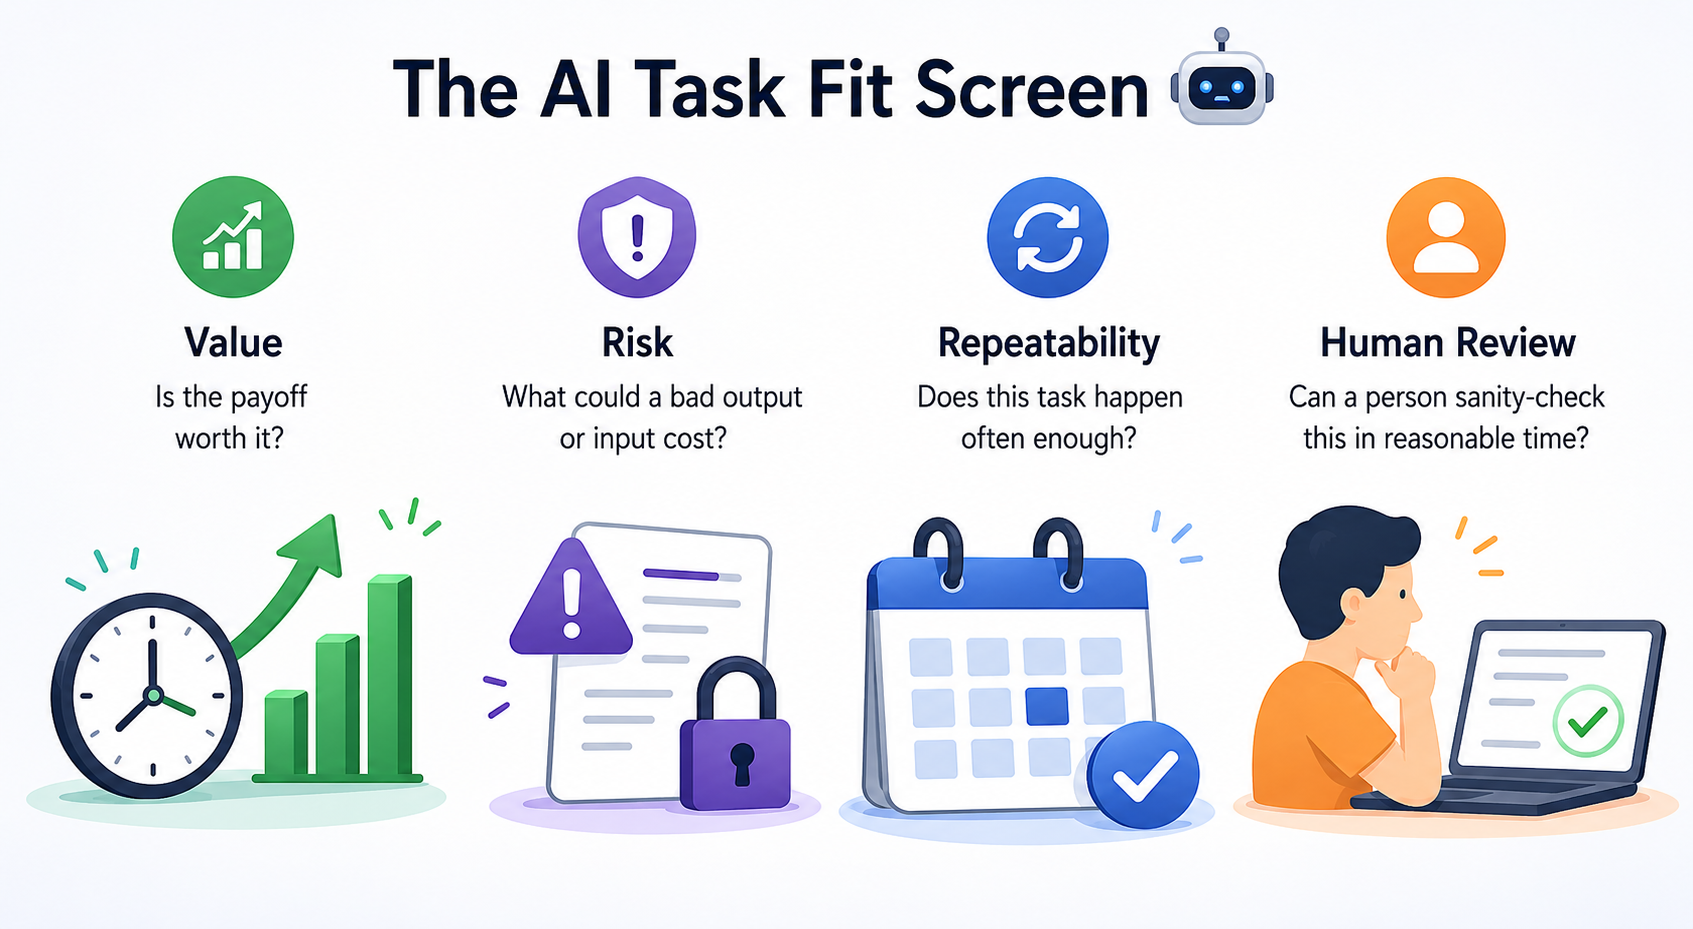
Value asks whether the payoff is worth it. Look for tasks where AI can meaningfully reduce time, improve consistency, or help you get unstuck. If AI shaves three minutes off something you do twice a year, the math doesn’t work.
Risk asks what a bad output could cost—and what a careless input could expose. A typo in an internal digest is recoverable; a fabricated growth rate in a board pack, a wrong number in a stakeholder readout, or an invented column in shipped SQL is not. Risk also runs in the other direction: never paste production data, customer PII, credentials, connection strings, or confidential business figures into an AI tool unless it's been explicitly approved for that use. Anything you submit may be retained or processed according to the tool’s data-use policy, so use customer data only in tools explicitly approved for that purpose. Run the Data Analyst AI Safety Checkpoint before you start.
Repeatability asks whether the task happens often enough to justify the setup. Recurring work—like a weekly metrics digest or a batch of survey-comment summaries—is usually a stronger candidate because you can reuse the prompt, refine the workflow, and compare results over time.
Human Review asks whether a person can actually sanity-check the output in reasonable time. If you can’t tell whether a figure is right or a query is valid, you can’t use the tool safely, no matter how good the writing sounds. And for anything that feeds financial reporting or an executive decision, "human review" means reconciling every figure against the source data, not just a quick read — which changes how fast and how cheaply a task can really be reviewed.
The trap most analysts fall into is anchoring on Value and ignoring the other three. High value plus high risk plus weak human review is not a pilot, it's a future wrong number in front of leadership.
Here’s what that sounds like in practice.
- Natalie: I want our first AI pilot to be the executive KPI commentary for the monthly board pack. Huge time save every month.
- Emily: Value's real, agreed. But run it through the screen with me. What's the cost if it invents a number or misreads a trend?
- Natalie: Could be a wrong figure in a financial-reporting pack that leadership acts on. Not great.
- Emily: And can someone sanity-check it without reconciling every figure against the warehouse?
- Natalie: Honestly, no. We'd still need to tie out every number to the source.
- Emily: So Value's high, Risk's high, Human Review's weak. Worth keeping on the list, but not our first one.
Notice Emily didn't kill the idea, she named the framework, walked the checks, and let the score speak. That's the move when someone anchors on a flashy candidate.
Picking Your First Pilot 🚦
Your first AI workflow should be deliberately boring: a task that scores well on all four checks, with low risk if it goes sideways. Recurring internal communication is a classic fit (the weekly metrics digest, a readout-template draft, a first pass at survey-comment theme tags) because the value is real, the risk is contained, the task repeats weekly, and you can eyeball the output against the dashboard in under a minute.
Then commit to a success criterion before you start, not after. Something concrete you can measure, like "cuts my metrics-digest drafting time in half across three consecutive weeks with zero figure corrections needed after reconciliation." Vague criteria like "saves time" let you talk yourself into a pilot that didn't actually work.
The takeaway for this unit: pick the task, not the tool, and let the AI Task Fit Screen tell you which task earns the pilot slot. The next step is a live conversation where you'll pressure-test five candidate analytics tasks against the Screen with a manager who's anchored on the flashiest option. Bring the framework by name and walk the checks out loud, that's where the skill actually gets tested.
