Introduction to Word Embeddings
Introduction to Word Embeddings
Welcome to the final lesson of the "Foundations of NLP Data Processing" course! So far, you've explored various techniques for representing text as numerical data, including Bag-of-Words and TF-IDF. While these methods are useful, they have a major limitation: they treat words as independent tokens without capturing their meanings or relationships.
In this lesson, we introduce word embeddings, a powerful approach to representing words as continuous-valued vectors that encode semantic meaning. Word embeddings allow models to understand relationships between words based on their context in large text corpora. Unlike traditional text representations, embeddings can capture synonymy, analogies, and contextual similarities.
Why Do We Need Word Embeddings?
Before diving into code, let's build an intuition for word embeddings by examining some limitations of traditional approaches:
-
Bag-of-Words (BoW) and TF-IDF ignore meaning
- In BoW and TF-IDF, words are represented as isolated units. Two words with similar meanings (e.g., "king" and "queen") have no direct relationship in these models.
- Example:
- "I love NLP" →
[1, 1, 1, 0, 0] - "I enjoy NLP" →
[1, 0, 1, 1, 0] - These two sentences are similar in meaning, but their vector representations don't capture this!
- "I love NLP" →
-
Word Order Matters
- "The cat chased the dog" vs. "The dog chased the cat" have different meanings, but traditional models treat them similarly.
-
No Concept of Context
- "Apple" (the fruit) and "Apple" (the company) are treated the same.
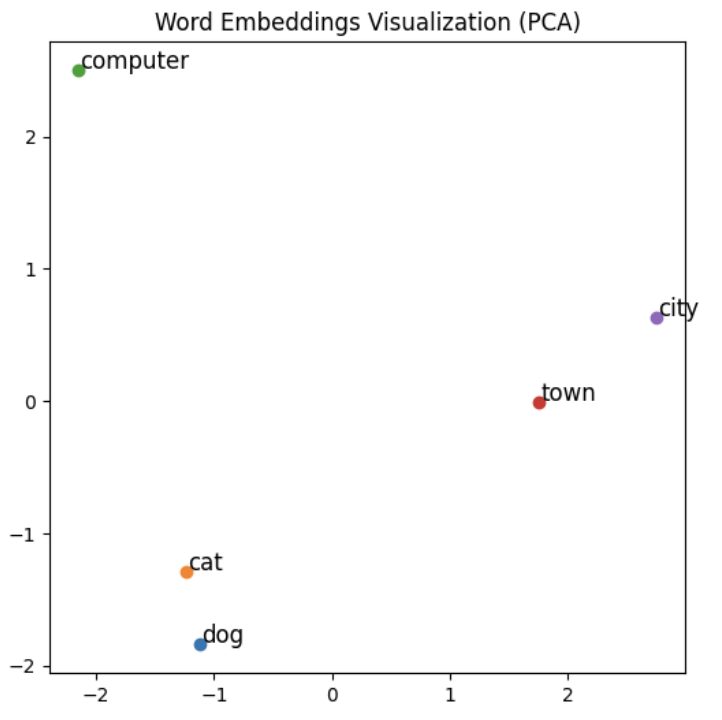
Word embeddings solve these issues by representing words as dense vectors in a multi-dimensional space, where words with similar meanings have closer representations.
Understanding Word Embeddings: The Core Idea
Word embeddings are generated by training models on large text data. The key idea is:
- Words appearing in similar contexts should have similar vector representations.
- Example: The words "king" and "queen" often appear in similar contexts (e.g., "the king rules the kingdom," "the queen rules the kingdom").
- Models like Word2Vec and GloVe learn to place these words closer together in the vector space.
There are different approaches to training word embeddings:
- Continuous Bag of Words (CBOW): Predicts a word based on surrounding words.
- Skip-gram: Predicts surrounding words given a target word.
- GloVe (Global Vectors for Word Representation): Utilizes word co-occurrence statistics from a corpus.