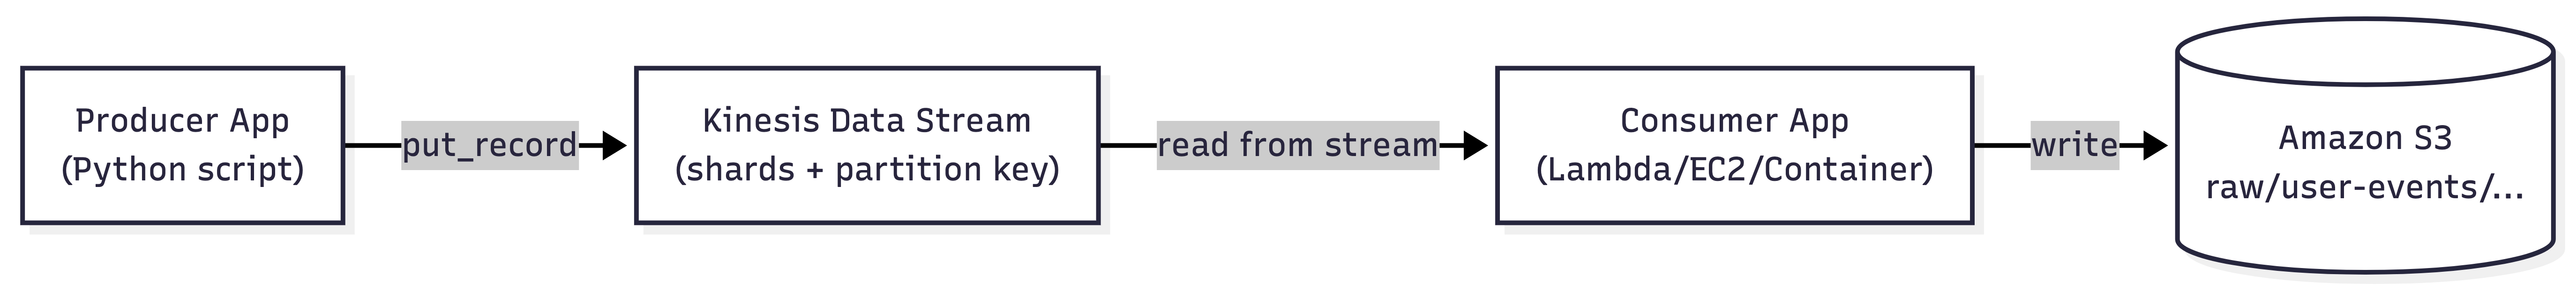
Streaming Ingestion with Kinesis
Introduction: Moving from Batch to Real-Time Ingestion
Welcome back! In the previous lesson, you built a strong foundation for your AWS data lake by designing a well-organized structure on Amazon S3. You learned how to create a multi-zone layout with raw, processed, and curated data, and you uploaded sample data using time-based partitioning. This setup is perfect for batch analytics, where data is collected and processed in chunks.
However, many modern applications need to process data as soon as it arrives. For example, you might want to analyze user activity on your website in real time, detect fraud as transactions happen, or monitor sensor data from IoT devices without delay. This is where real-time data ingestion becomes important.
To enable real-time data flows into your data lake, AWS offers a service called Amazon Kinesis Data Streams. Kinesis allows you to collect, process, and move data continuously, so you can react to new information instantly. In this lesson, you will learn how to create a Kinesis Data Stream using Python. This is the first step in bridging the gap between real-time data sources and your S3-based data lake.
Kinesis Data Streams: Key Concepts
Before you start working with Kinesis, let’s clarify a few important concepts. A Kinesis Data Stream is a managed service that lets you collect and transport data records in real time. Think of it as a pipeline that carries small pieces of data — called records — from producers (like your application or website) to consumers (such as analytics tools or storage systems).
Each stream is made up of one or more shards. A shard is like a lane on a highway: it determines how much data can flow through the stream at once. If you need to handle more data, you can add more shards, just like adding more lanes to a road allows more cars to travel at the same time. For most beginner projects, starting with a single shard is enough.
When you create a Kinesis stream, it goes through different status phases. At first, the stream is in the CREATING state while AWS sets up the necessary resources. Once it is ready, the status changes to ACTIVE, and you can start sending and receiving data. It is important to wait for the stream to become ACTIVE before using it; otherwise, your application may run into errors.
Here is a quick summary of the key terms:
- Stream: The main resource that collects and transports your data records.
- Record: A single piece of data, such as a JSON object or a string.
- Shard: A unit of capacity within the stream. More shards mean more data can be handled at once.
- Status: The current state of the stream, such as
CREATINGorACTIVE.
Understanding these concepts will help you as you start working with Kinesis and connect it to your data lake.