Writing Effective Prompts
Writing Effective Prompts ✍️
Now that you've picked a task for AI, the next move is harder and more useful: asking for the output in a way the model can actually deliver. A vague prompt produces a vague draft — a generic discovery follow-up or a mushy RFP answer — which then costs you twenty minutes editing, the exact time you were trying to save. A strong prompt brings the important details upfront so the first output is much closer to usable. This unit gives you a framework for writing strong prompts, a method for turning fuzzy pre-sales requests into specific deliverables, and a habit for improving prompts after a weak first try.
By the end, you'll be able to:
- Use the RACE framework to structure clear, complete prompts.
- Translate vague pre-sales requests into specific AI-ready deliverables.
- Refine weak outputs by tightening the prompt instead of simply asking the model to "try again."
The RACE Framework 🏁
Treat every prompt like a brief you'd hand to a sharp new teammate who's never seen your product, your deal, or your prospect. To improve consistency and response quality, use the RACE framework—a four-step model that reduces guesswork.
- R - Role (Who is the AI?): Assign a persona or expertise level. Telling the AI it is an "expert solutions engineer" or a "senior technical writer" can steer tone and framing, but it does not give the model verified knowledge. Provide approved source material or tool access when the response must rely on specific facts.
- A - Action (What do you want?): State the exact task using clear, directive verbs. Instead of "look at this," use "summarize," "draft," "critique," or "rewrite."
- C - Context (Why does it matter?): Provide the background, target audience, and constraints. This is where you mention what stage the deal is at, who will read the output, and any "guardrails" (what to avoid — like claiming a capability or certification you haven't verified).
- E - Execute (How should it look?): Specify the formatting, length, and style. Do you want bullet points, a 150-word follow-up email, or a table? Providing an example of the desired style can improve consistency and help the output more closely match your intent, but you still need to verify it.
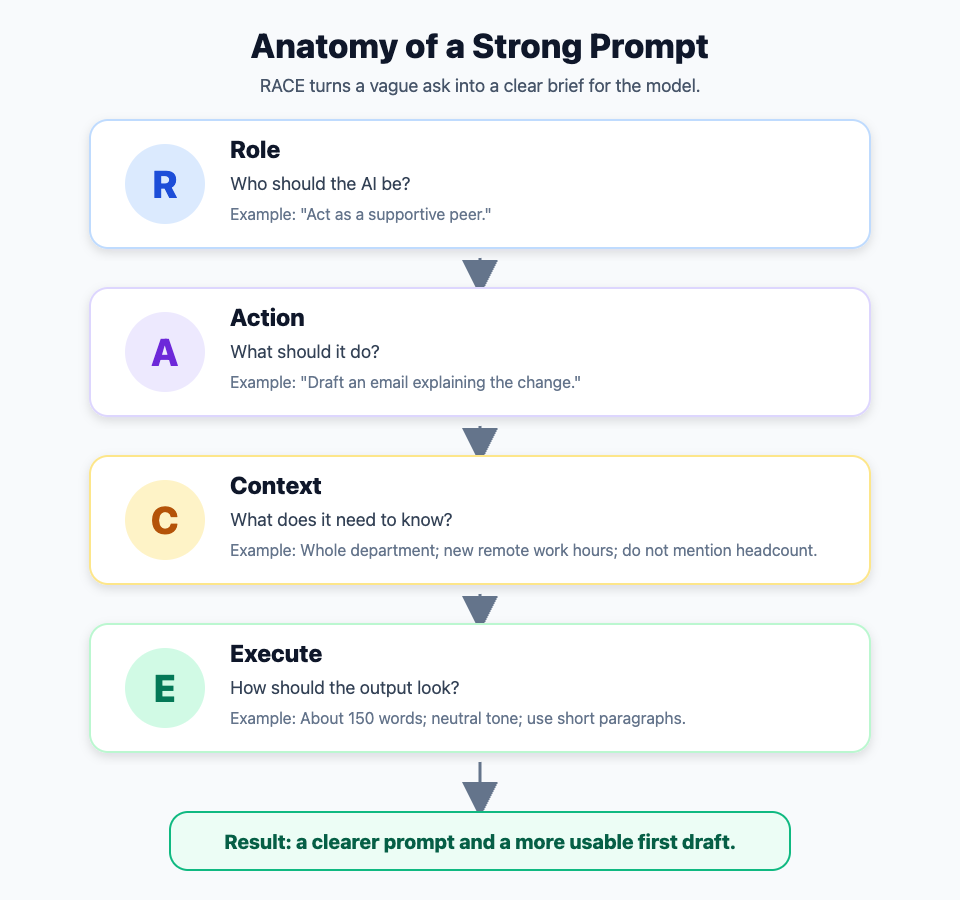
The reason this works ties back to how language models operate: they predict based on the context you give them. Sparse context leads to generic predictions — and on a capability or compliance topic, generic predictions are where invented specs creep in. A structured RACE prompt leads to sharper, professional results.
Turning Vague Requests Into Specific Deliverables 🎯
Most pre-sales requests show up vague. Your AE forwards a one-liner, or a stakeholder drops "can you draft something" in Slack. The instinct is to type that vague phrase straight into the AI.
Don't.
Translate the vague request into the RACE components before you write the prompt. Let's look at an example:
- Priya (AE): Can you draft something for the prospect about our new integration?
- You: Happy to. Quick check so I nail it on the first pass: what's the goal here (Action), and who exactly is reading it (Context)?
- Priya: It's a follow-up email to their technical evaluator, about 150 words (Execute). Explain how the integration handles their data sync without committing to anything we haven't verified (Context/Constraints).
- You: Got it. Should I write as a neutral solutions engineer or a more formal technical lead (Role)?
- Priya: Solutions engineer voice, keep it precise.
Notice you didn't open the AI tool yet. You pulled the missing Role, Context, and Execution details out of the AE in thirty seconds. Because you have the RACE elements ready, your first draft will be significantly more accurate.
Refining The Prompt After The First Output 🔧
Even a strong RACE prompt rarely lands perfectly. The first output is diagnostic data, not a verdict. Read it and ask which part of the framework was thin:
- If the tone is too robotic: Your Role was too broad.
- If the model missed the point: Your Action wasn't specific enough.
- If it included something it shouldn't have (like a capability or certification you never verified): Your Context may have lacked constraints. Tighten them to reduce the risk, then verify every claim against approved sources.
- If the structure is messy: Your Execute instructions were too loose.
Don't argue with the model in chat or ask it to "try again, better." Rewrite the prompt itself, tightening the RACE elements that failed, and re-run. Constraints lower the risk of fabrication but cannot guarantee accuracy, so retain source-based human verification before you use any capability, integration, or compliance claim. This gives you a reusable prompt for the future. Save the strong version in a personal prompt library. Future-you will thank present-you.
The takeaway: prompts are briefs, not questions. Structure your request using RACE, then refine based on what the first output reveals. Next, you'll move into a live practice session where you'll apply these habits to a sensitive pre-sales scenario.
